VeriDoc — Insurance Document Fraud Detection
Decision-support platform for insurance investigators that combines forensics, OCR, consistency rules, cross-document checks and trusted-source verification into one explainable evidence record.
Built by Redoan Uzzaman, Full-Stack Developer & AI Engineer.
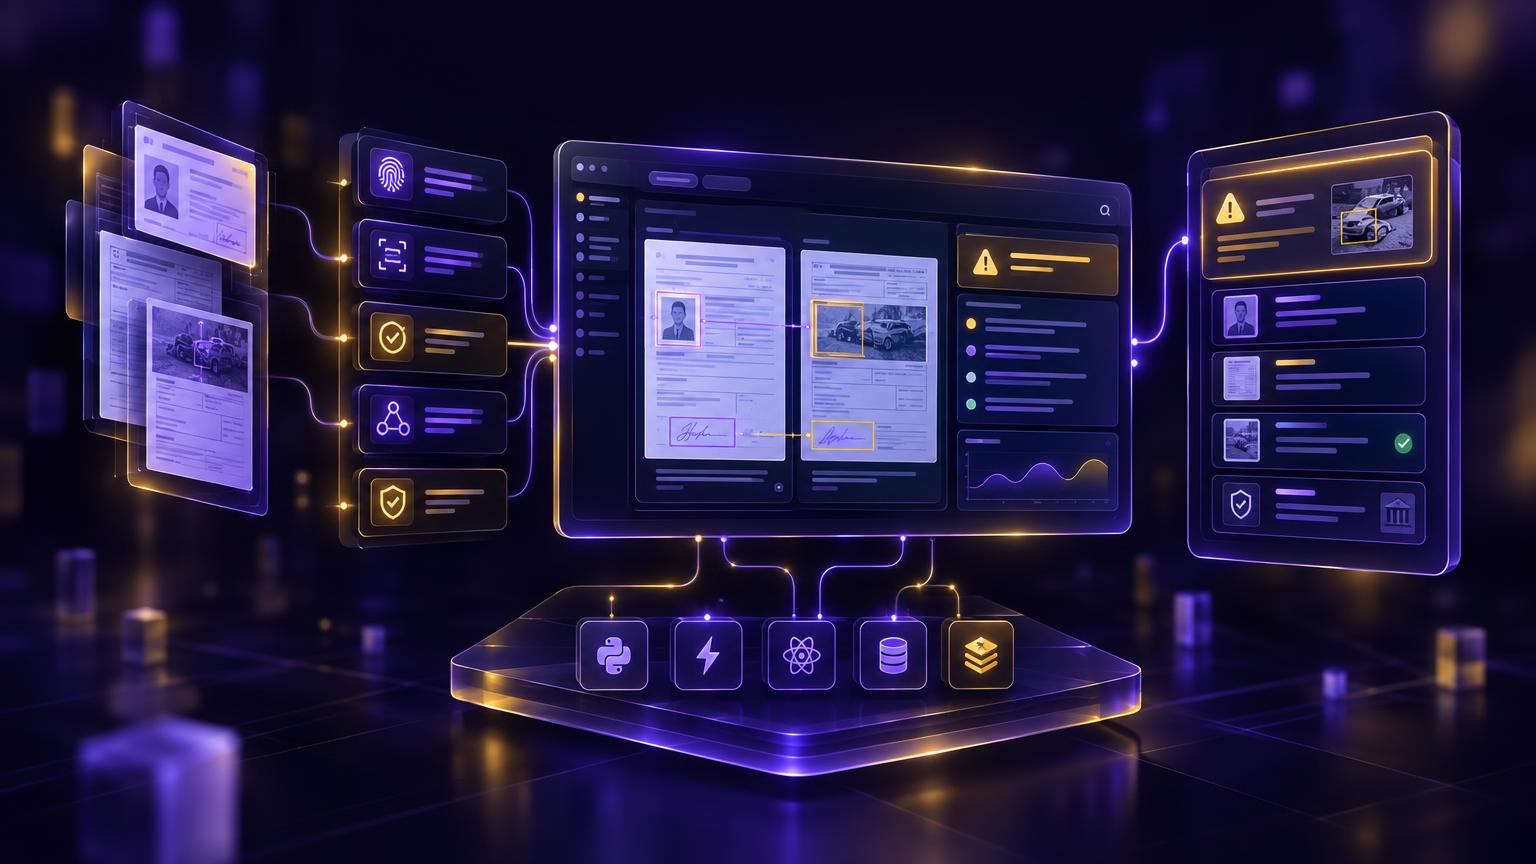
Overview
VeriDoc helps insurance investigators triage claim documents such as medical bills, invoices, prescriptions, identity papers, vehicle documents, repair estimates and police reports. It never declares a document genuine or fraudulent. Every finding carries a severity, a calibrated confidence, the measured evidence and the detector version, and the final claim decision is always recorded against a named human.
How it works
Uploads go through a 14-stage analysis pipeline on background workers:
- PDF structure: metadata, revision history, producer software, data appended after the end-of-file marker, and embedded JavaScript.
- Image forensics: error-level analysis, sensor-noise residuals, copy-move detection, JPEG-ghost compression history and resampling checks. Region significance comes from a sliding-window statistical test.
- Typography: baseline, size and stroke analysis. For digital PDFs it reads the exact font of each character.
- OCR and extraction: text from the PDF layer or Tesseract, with a bounding box for every field.
- Rules: 20 deterministic checks, including line-item arithmetic, tax rates, date logic, VIN check digits, IBAN mod-97 and duplicate content across claims.
- Cross-document comparison: fields are compared within a claim bundle using type-aware pairing policies.
- Synthetic media and trusted sources: both sit behind provider interfaces.
Architecture
A Next.js 15 investigator console talks to a FastAPI backend through an httpOnly-cookie proxy. RQ workers process the queue, PostgreSQL stores 25 tables, and S3-compatible storage keeps originals immutable and separate from derived artifacts. Four roles (investigator, claims officer, reviewer, administrator) are enforced by the API, and every action is audited. A deterministic seeder builds a demo with 10 claims and 22 generated documents that contain real, detectable anomalies. The backend has 174 automated tests.
Key Features
- 14-stage forensic, OCR and rules pipeline
- Image forensics: ELA, noise residuals, copy-move and JPEG-ghost analysis
- 20 deterministic consistency rules (arithmetic, dates, VIN, IBAN, duplicates)
- Cross-document field comparison with type-aware pairing policies
- Explainable triage score; claims cannot be approved while high-severity findings are unresolved
- Role-based access for investigators, claims officers, reviewers and admins, with a full audit log
- Pluggable providers for OCR, synthetic-media detection and verification
Tech Stack
- Python
- FastAPI
- Next.js
- TypeScript
- PostgreSQL
- Redis
- SQLAlchemy
- Tesseract OCR
- MinIO
- Docker
Want something like this built?
Redoan Uzzaman takes on AI, automation and full-stack projects for clients worldwide.